The repository is a complete description of what the system does and a total blank on what it was supposed to do. Which two approaches were tried first. What that abstraction is defending against. Why the obvious refactor is a trap. None of it is in the code, because none of it ever could be, and it’s the part that costs six weeks when the person holding it leaves.
The commit message holds one sentence about a change, written at the end of the day it happened, with the alternatives already forgotten. The wiki holds a description of how a module works, which was accurate for one sprint and is now actively misleading, so people stopped trusting it and then stopped writing it. The decision records made it to number four.
They usually do. Writing one asks you to recognise a decision as a decision while you are still standing inside it, and to file it under a name that only makes sense once it’s over. It is the same mistake as premature optimisation, made a layer up: you commit to a structure at the moment you know least about what it has to hold.
Meanwhile the actual reasoning is intact and in perfect condition, distributed across three or four people, retrieved by walking over and asking. That works right up until it doesn’t, and the failure is never gradual: it’s a resignation, a reorganisation, or a contractor arriving on Monday.
A decision becomes a node. So does the driver that forced it, the option you didn’t take, the consequence you accepted, and the component that now has to live with all three. The lines between them are typed and directional and you name them yourself: influenced by, supersedes, constrains, rejected because, implemented in.
The consequence is that the discarded option stops being a thing somebody remembers arguing about. It is written down, attached to the decision that beat it, carrying the reason it lost. Six months later, when the obvious refactor is proposed for the third time, the answer is a node rather than a senior engineer sighing. That single behaviour is most of the value here, and no folder of numbered Markdown files can produce it, because the relationship between one decision and the next is exactly what a directory can’t express.
It all lives in your repository, where every node is a Markdown file with YAML frontmatter in an ordinary directory, so it commits, branches, diffs and reviews with the code it describes. A decision changing in the same pull request as its implementation is the only form of documentation review anybody has ever actually done twice.
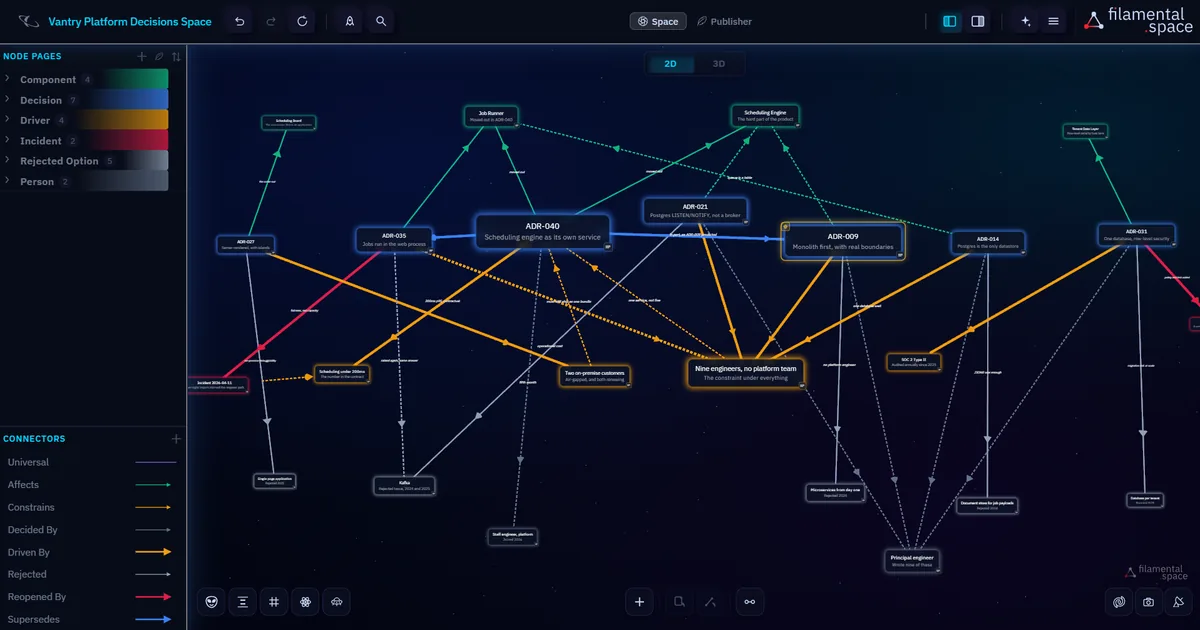
An invented company of nine engineers building field-service scheduling. Its space holds the architecture decisions, the options it rejected, the drivers those decisions rest on, the components they touch, the incidents that followed and the engineers who wrote most of it. It isn’t documentation, and there’s no description of the system anywhere in it.
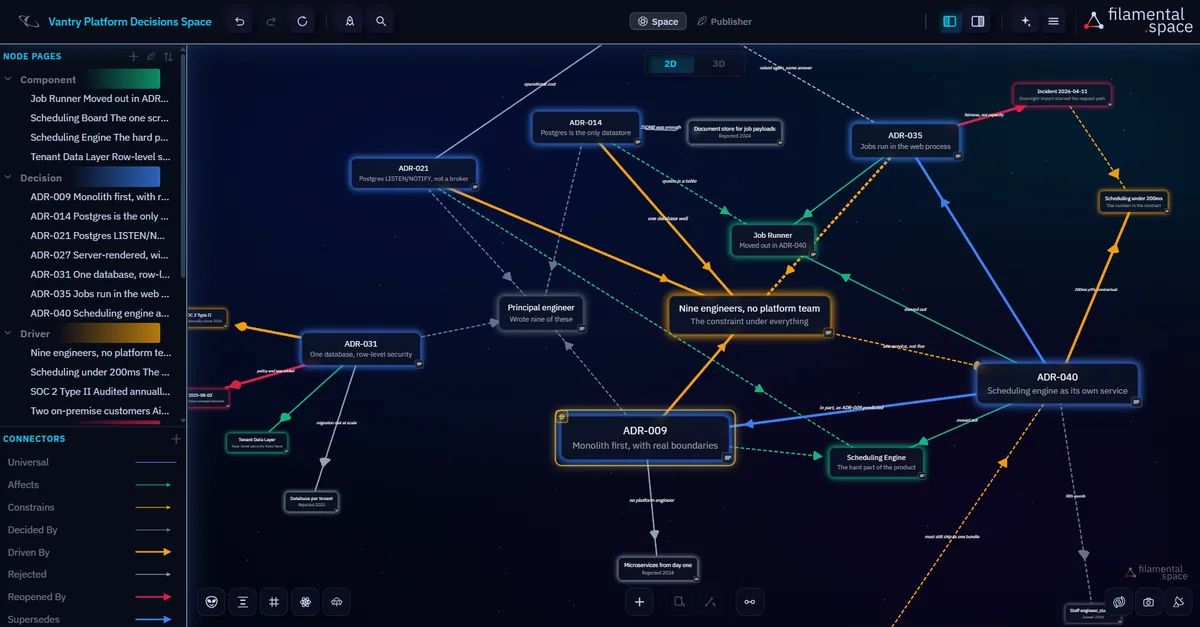
Kafka is a node, and it was rejected twice. Once in 2024 and once in 2025, by two engineers who didn’t know about each other. The second time it was raised nobody could find the first rejection, and the argument was had again from the beginning over four days. That is the specific waste, and it’s the one thing a repository full of code can’t help with, because the code is evidence of what was built and silent about what was refused.
One driver carries four decisions. "Nine engineers, no platform team" is a node, not a sentence buried inside a record, and four separate decisions point at it. So the question "what changes if we hire an infrastructure person" has an answer that takes one click instead of a week: these four things become worth reopening, and nothing else does. That isn’t a documentation feature but the thing you can’t do when the same fact is retyped into four different pages.
The payoff is the last node in the chain. A staff engineer joined in February, read the space instead of asking, and wrote the decision that split the scheduling engine out in their fifth month. It took six weeks against a five-month estimate, because the 2024 decision had written down where the seam was and why. That is what the reasoning is worth, and it’s only worth it if it survived the two years between being written and being needed.
There’s a board open on a second screen in most teams we have talked to, holding what is being worked on this week and who has it. That’s a hard job done well by tools built for it, and nothing here is aimed at any of them. We wouldn’t want the work in this either, since a decision record that starts accumulating tickets has stopped being a decision record.
The exception is the moment something is wrong. At ten past two a single customer's catalogue import saturates the shared thread pool and request latency goes to eleven seconds for everybody, and the question in the channel isn’t yet what to do about it but what is actually going on. Nothing has changed and nothing is broken, which is the disorienting part, because the system is doing exactly what somebody decided it would do at a size they didn’t have when they decided it.
That’s a question about structure, and it’s the one this shape answers quickly. The incident sits against the decision that produced the behaviour, which sits against the constraint that made it reasonable at the time, and against the approach that would have avoided it, raised twice and refused twice for reasons somebody bothered to write down. Whether any of that is worth having depends entirely on whether it existed before the night you needed it, which is the argument the rest of this page is making.
It won’t page anybody, hold a runbook or tell you what to do next, and by the morning the useful direction has reversed anyway. The incident stays attached to the decision it undermined, so the record reads as reopened with a reason rather than quietly wrong, and the next person to propose the thing that was refused finds the refusal instead of the argument.
Every documentation tool your team has adopted has died, and anyone telling you this one is different because of its interface is selling something. What actually changes the odds is what you point it at. Descriptions rot fast, because a page explaining how a module works is wrong within a sprint and wrong in a way that is worse than absent. Decisions barely rot at all: the note recording that two approaches were rejected in March, and why, is still true in three years, because the past doesn’t change.
So the scope is deliberately narrow. It doesn’t want your API reference, which your types already generate better. It doesn’t want a tutorial, a runbook or a description of the folder structure. It wants the fifty or so choices that explain why the system looks like this, which is a volume a team can actually maintain, and which is the exact material nobody can reconstruct by reading the source.
There’s no server, no account, no sign-in and no telemetry of any kind. It’s a desktop application reading a directory, so it adds nothing to your infrastructure and nothing to your vendor list. It won’t review code, run CI or generate documentation from your types. Keep whatever does those.
Rather than a case study about a company you can’t inspect, here’s one you can. Every page in the Help section is built from a Filamental space by a script in the website's repository. One Markdown file per topic, with the relationships between topics driving the cross-links you see at the bottom of each page, and the same space also being the source of the help built into the application. Two consumers, one set of files, and no possibility of the website and the application disagreeing about how something works.
That’s the whole pattern, and it isn’t a special integration. A space is a directory of Markdown with structured frontmatter, so anything that can read a directory can consume it: a static site generator, a build step, a script, or the agent you have open right now.
A coding agent with your whole repository in context is extremely good at what the code does and structurally incapable of knowing what it is for. So it proposes the clean refactor that removes the workaround, and the workaround was load-bearing for a reason that was discussed once, in a meeting, in 2025.
Filamental ships a local MCP server, so Claude Code, Cursor or anything else speaking the protocol can search the space, read a decision, follow its relationships and write new ones back, running on your machine against your directory with nothing in between. The repository tells it what, while this tells it why, and why not. Those are different questions and only one of them is answerable from source.
The human version still matters. A new engineer's first fortnight is almost entirely spent reconstructing decisions rather than reading code, and an incoming contractor never gets that fortnight. When somebody outside needs the picture, a client, an auditor or an acquirer, the space can be sent as a link or a single file that opens in a browser with the structure navigable inside it, and they install nothing.
You don’t begin with a blank screen. A Template is a starting vocabulary, the kinds of thing that exist in a job and the ways they relate, so the categories are already there and already coloured when you make a space.
A starting point, not a schema you’re stuck inside. Rename a category, add one, delete the ones you never use. Nothing stops you using more than one in a space. API Design and Capacity & Scaling are the two next door most often reached for, and teams shipping models rather than services tend to want the AI Engineering set instead.
Everything above except the sending is free permanently, with no account and no card, and there’s no per-seat tier at any point. That’s the failure mode of every documentation tool a team has ever cancelled: the license count grows, somebody in finance asks what it is for, and the honest answer is that four people use it.
Here it doesn’t arise, because the structure is Markdown in your repository. Anybody can read it in an editor, on your code host, or through an agent over MCP, without installing anything at all. The desktop application is for building and navigating it visually, which in practice two or three people do.
Spaces are unlimited and the bridges joining them are free, so a system becomes a few linked spaces rather than one diagram nobody can read: the domain in the first, the delivery and infrastructure decisions in the second, the integrations in the third, each holding twenty nodes. The paid tier is $120 a year, or $12 a month, and buys handing a space to somebody who doesn’t have Filamental, which for most teams is a client, an auditor or an incoming contractor.
It’s the same idea with the missing half added. An ADR is a numbered file in a directory, which means the relationship between a decision and the component it constrains, the driver that forced it and the decision it superseded exists only as prose somebody has to read in order. Here those are typed relationships you can walk in both directions, so opening a component shows every decision that shaped it without anybody having read the whole directory.
Yes. Filamental ships a local MCP server, so Claude Code, Claude Desktop, Cursor or anything else speaking MCP can search the space, read a node, follow its relationships and write new ones back. It runs on your machine against your folder with no cloud service in between. Your repository already tells an agent what the code does; this is where it finds out why, including which approach was tried and abandoned.
Yes, and most teams put it there. Every node is a Markdown file with YAML frontmatter in an ordinary directory, so it commits, branches, diffs and reviews like anything else in the tree. A decision changing in a pull request alongside the code that implements it is the only version of documentation review that has ever actually worked.
Partly, and anyone claiming otherwise hasn’t run a team. What changes the odds is scope and location: this holds decisions rather than descriptions, and decisions are far more stable than the code implementing them. A page describing how a module works is wrong within a sprint, whereas a note saying which two approaches were rejected and why is still true in three years. That is the part nobody can reconstruct from reading the code.
No. Because the structure is Markdown in the repository, anyone can read it in an editor, on a code host, or through an agent connected over MCP, without installing anything. The desktop application is what you use to build and navigate it visually, and in most teams two or three people do that while everyone else reads. There is also no per-seat pricing, so team size doesn’t change the cost.
The Personal plan is free permanently, with no account and no card, and there’s no per-seat tier at any point. Spaces are unlimited and the bridge nodes joining them are free, so a system becomes a few linked spaces rather than one unreadable diagram, each holding twenty nodes. The paid tier is $120 a year, or $12 a month, and buys one thing: sending a space to somebody who doesn’t have Filamental, which for most teams means a client, an auditor or an incoming contractor.
One decision is enough to find out whether this suits how you work. Free, no account, no card, and it lives in your repository like everything else.